


 ClaudeOpenAIGeminiOpenRouterVeniceDeepSeekxAI
Every model you pay for, in your editor
Claude Code, Codex, OpenClaw and every SDK keep the request format they already send. Only the base URL and the model ID change.
Set up your editor
Jatevo connects the provider accounts you already have, Claude, OpenAI, Gemini, OpenRouter, Venice and any OpenAI-compatible endpoint, behind one URL and one key. Change the model ID, not your code.
Explore the APINothing to install. Your keys, your use.
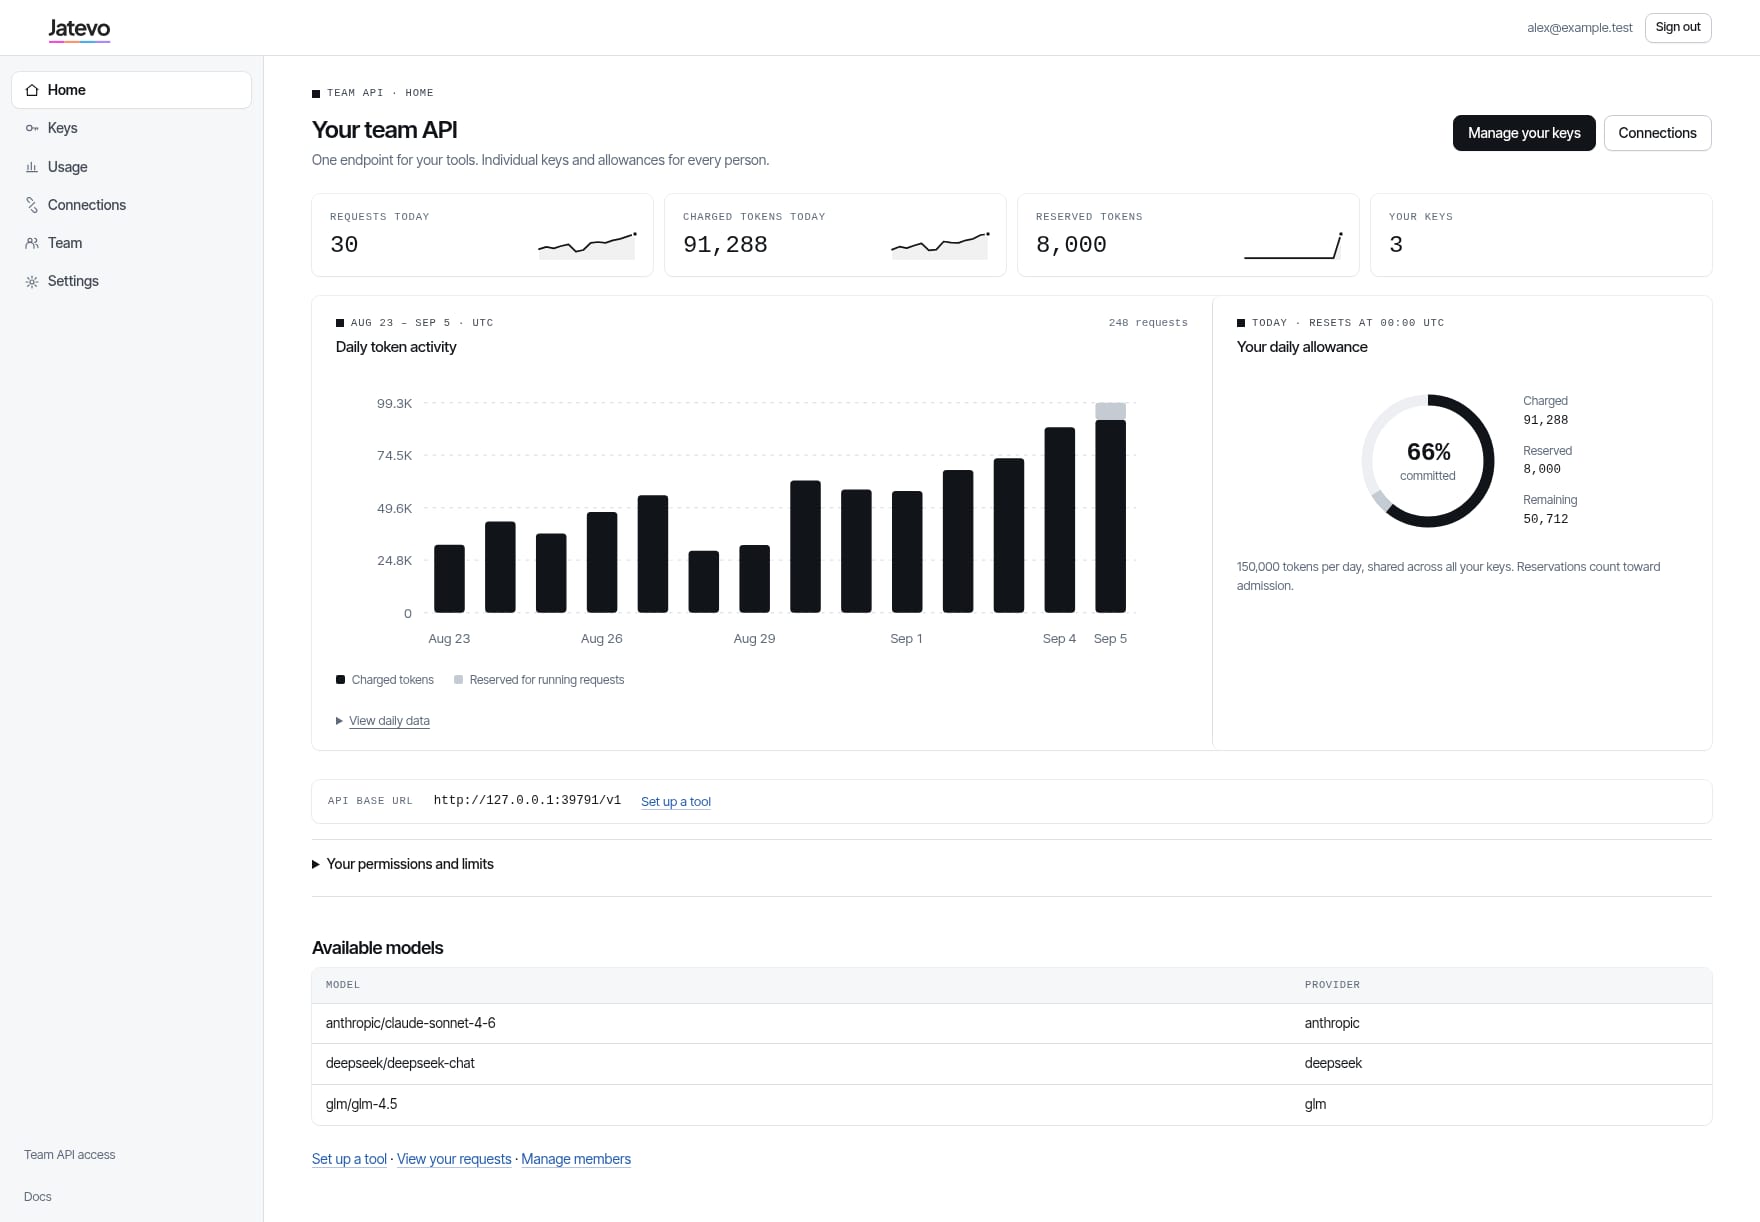
Daily allowance
91,288
of 150,000 tokens today
Reserved before dispatch
Keys
3 active
one per tool, one allowance shared
Revoke one, nothing else stops
Usage by provider
775K
charged tokens, last 14 days
Every request in a table, CSV export
Team
5 members
allowances across every key they hold
Owner, administrator, member
Connections
3 providers
credentials encrypted, never shown again
Model IDs carry their provider
01 · Who it is for
ClaudeOpenAIGeminiOpenRouterVeniceDeepSeekxAIClaude Code, Codex, OpenClaw and every SDK keep the request format they already send. Only the base URL and the model ID change.
Set up your editor
One key per person
jv_…8f2a91,288of 150,000jv_…c19d412,900of 600,000jv_…0e7718,400of 50,000jv_…3b6c6,120of 30,000One connection per provider, one key per person, allowances that apply across every key a member holds.
Invite your team
$ npm start
Jatevo 0.1.0 listening on http://127.0.0.1:8700Node.js 24 and one SQLite file on your own machine, beside the models you serve yourself. No dependencies to install, nothing that phones home, MIT licensed.
Run it on your own machineEvery person and every workload gets its own key. A key carries its own daily allowance, request rate, concurrency and output cap, and the member's allowance applies across every key they hold. Revoke one key and nothing else stops.
How keys and allowances workIllustrative figures. The console shows your own.

Key, member, model, daily allowance, rate, concurrency and output are checked inside one transaction before a request leaves. Parallel calls cannot all spend the same remaining room.
02 · Developers
One base URL, one key, the request format your tool already sends. The model ID names the provider, so the gateway never guesses.
curl https://jatevo.ai/v1/chat/completions \
  -H "Authorization: Bearer $JATEVO_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "openrouter/anthropic/claude-sonnet-4.5",
    "messages": [{"role": "user", "content": "Hello"}]
  }'
Two routes to one model stay two names. Nothing is inferred from a display name, so a key permitted on one provider can never select another provider's model by accident.Routing, from the API referenceRead the routing rules
03 · Routing
Your tools keep the SDK and the request format they already use; only the model ID changes, and it says where the request goes.
| Model ID | Provider | Format | Sent to the provider as |
|---|---|---|---|
| anthropic/claude-sonnet-4-5 | Claude API | Messages | claude-sonnet-4-5 |
| openrouter/anthropic/claude-sonnet-4.5 | OpenRouter | OpenAI Chat | anthropic/claude-sonnet-4.5 |
| venice/llama-3.3-70b | Venice | OpenAI Chat | llama-3.3-70b |
| gemini/gemini-2.5-pro | Gemini API | Gemini | gemini-2.5-pro |
| deepseek/deepseek-chat | DeepSeek | OpenAI Chat | deepseek-chat |
04 · Providers
API credentials are stored encrypted and never shown again. Each connection answers in the formats its provider implements; nothing is claimed for an endpoint that does not implement it.
05 · Your keys, your use
The keys you mint are for your own tools and your own team. Jatevo is not a place to resell access, and it moves no money. If a marketplace that allows it accepts a key you mint here, that arrangement is between you and that marketplace.

Not for resale
06 · Status
An early, honest cut. The gateway core is complete and tested; the layers that turn one console into a hosted service for many teams come next, in this order.
07 · Run it
MIT licensed. Node.js 24, one SQLite file, nothing to install. The whole gateway on your own server.
The gateway at this address, run by the people who write it, with the same admission and accounting.
One isolated deployment per team: its own credentials, its own encryption secret, its own domain and backups.
08 · Source
The hosted gateway runs the code on the right, unchanged. Clone it, set it up, start it.
Install guidegit clone https://github.com/lucacadalora/open-gateway-jatevo.git cd open-gateway-jatevo cp .env.example .env npm run setup npm start